






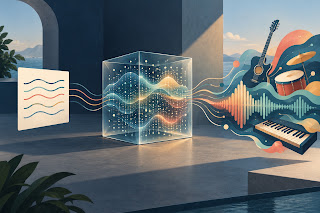
A few years ago, “AI music” mostly meant short, robotic loops that nobody wanted to listen to twice. Today you can type a sentence like “upbeat indie pop about a summer road trip, female vocals” and get a full song with verses, a chorus and a singer in a couple of minutes. For many people, that feels a little like magic.It isn’t magic, though, and understanding what is happening behind the button makes you much better at using these tools. This guide explains, without the jargon, how AI music generators work, what you can control, where they still fall short, and how to get better results from them.
Daftar Isi
What an AI music generator is
An AI music generator is software that creates new audio from an instruction. The instruction is usually a text prompt, but it can also be your own lyrics, a reference track, an image or a short video clip, depending on the tool. The output is an original piece of music, sometimes instrumental, sometimes with sung vocals.Popular examples range from simple web apps to full creative suites. On Creatune.ai, for example, the AI music generator accepts either a short description or complete lyrics and returns finished tracks, while all-in-one platforms like AIMusicCreator.io combine song generation with everyday audio utilities such as cutting, changing volume or finding a track’s key and tempo.
How the technology works, in simple terms
Step 1: Learning from huge amounts of music
Like other generative AI, music models are trained on very large collections of audio, often paired with descriptions such as genre, mood, instruments and tempo. During training, the model is not memorizing songs to play back. It is learning patterns: how a drum groove usually supports a bass line, how a chorus tends to lift in energy, how a voice moves from one note to the next.
Step 2: Turning sound into something a model can handle
Raw audio is enormous. One minute of high-quality sound contains millions of tiny measurements. To make it manageable, most systems first compress audio into a much smaller set of “tokens” or a compact internal representation, a bit like turning a long video into a series of key frames. The model works in this compressed space and a separate component turns the result back into listenable sound at the end.
Step 3: Reading your prompt
When you type “melancholic lo-fi hip hop with soft piano,” a language component converts your words into a numerical description the music model understands. Words like “melancholic,” “lo-fi” and “piano” each push the result in a certain direction. If you provide lyrics, the system also has to plan where each word falls in time so the singer can pronounce it on the beat.














Beri Komentar